This feature is in and is only available to enrolled organizations. To enroll your organization, contact your Cockroach Labs account team or sign up for the preview. This feature is subject to change.
- Continuous, CockroachDB-aware monitoring that builds up context about your cluster over time.
- Intelligent alerting and automatic investigations. When Aegis detects an anomaly or a potential issue, it opens an investigation and gathers the evidence itself, so you do not start from square one.
- Recommendations that include supporting evidence and, where applicable, SQL for you to review and run. Recommendations are the primary information channel that you should pay attention to.
- Periodic reports that explain what is happening on the cluster.
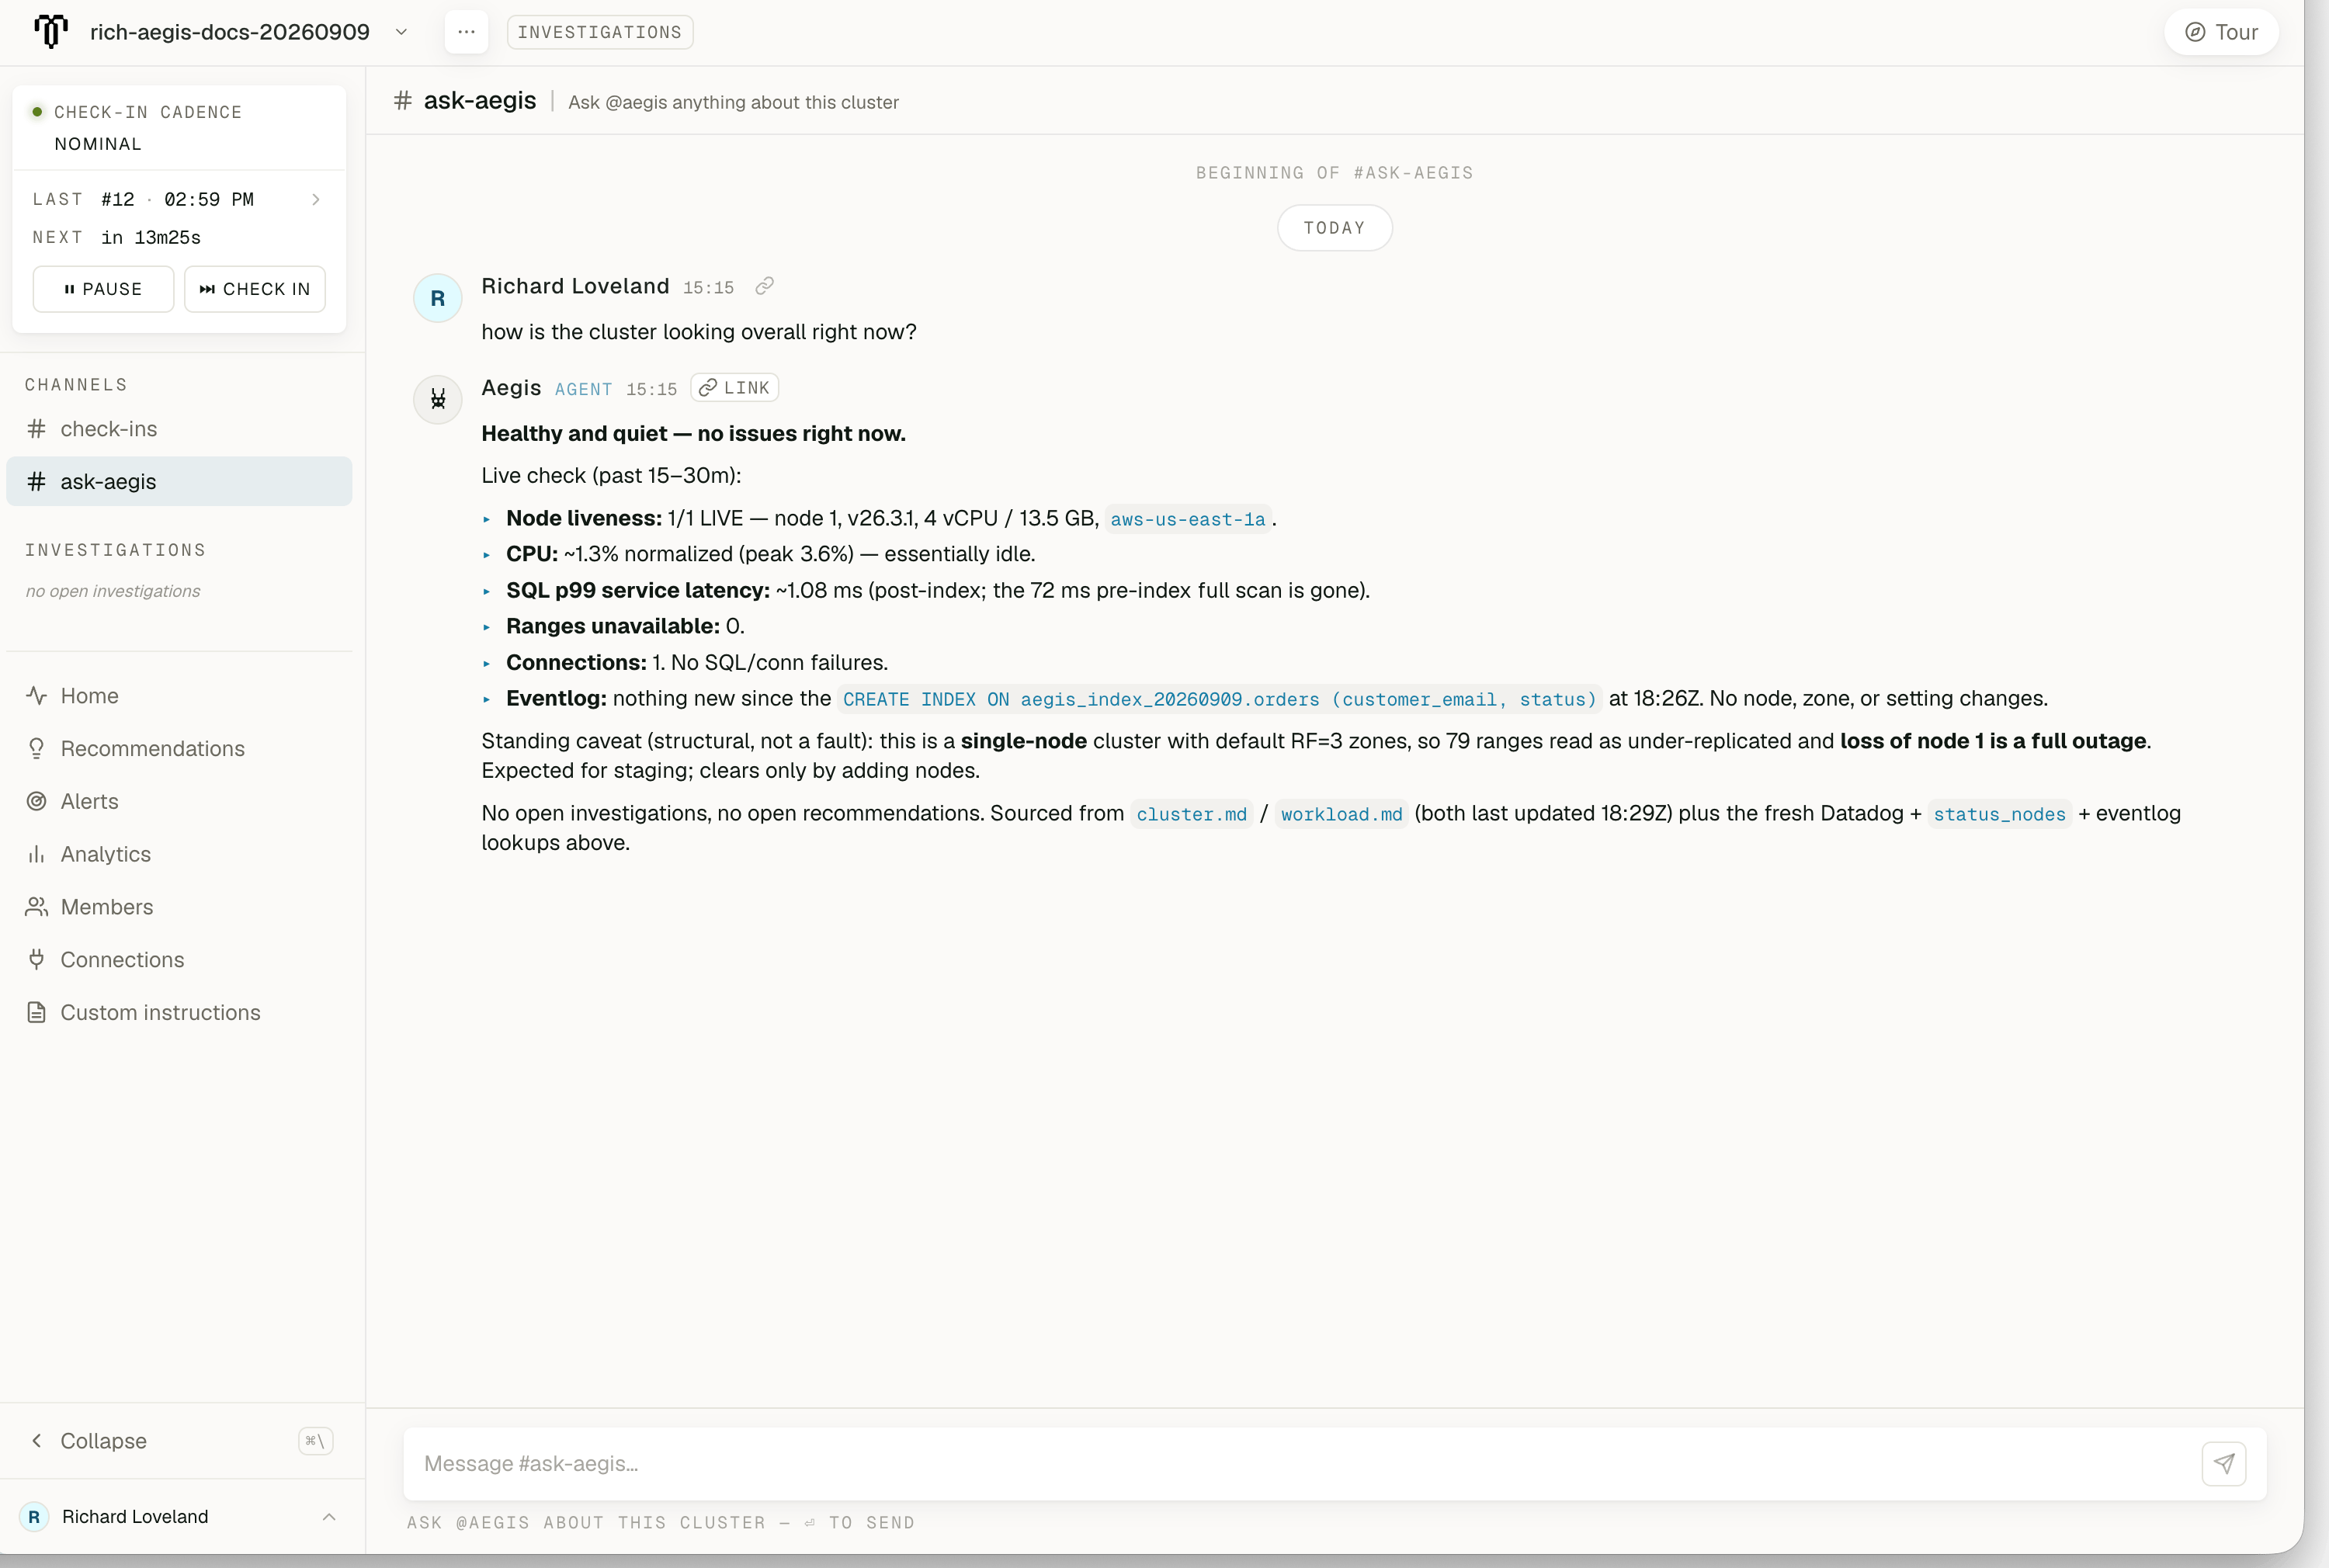
- Ask Aegis, a conversational user interface for questions about your cluster.
- An MCP endpoint that lets your own agents access Aegis’s analysis.
By default, Aegis’s access to your cluster is read-only. It can only make recommendations about changes to make, which you can review and apply through your normal change process.
- How Aegis monitors your cluster through check-ins.
- How alerts and investigations turn detected conditions into analysis.
- How to read reports and recommendations.
- How Aegis uses accumulated context, and how to steer it with custom instructions.
- How to use the Aegis web UI and Ask Aegis.
Automatic monitoring through Check-ins
Aegis reads cluster signals through a connection to your cluster, and records its analysis in a hosted service maintained by Cockroach Labs. A check-in is a periodic review of a cluster and its workload. During a check-in, Aegis compares current signals with its previous observations, refreshes its reports, and investigates conditions that warrant attention. Each check-in starts with Aegis reading the latest cluster and workload reports and any open investigation records, then using its tools to observe the cluster. What it records feeds the next check-in:- Reports carry updated cluster and workload context forward.
- Investigations track deeper analysis of anomalies.
- Recommendations surface actions for you to take.
A check-in can carry an existing report forward unchanged. To find out whether a report reflects a recent change, check the observation times inside the report. When you retrieve reports through MCP, each report’s
changed, created_at, and version_id fields show whether that check-in rewrote it. For details, see Verify the MCP connection.Intelligent Alerting and Investigations
Aegis uses alert rules and investigations to turn detected conditions into analysis and possible next steps.- An alert rule defines a condition to evaluate against cluster metrics or SQL query results.
- An alert records that a rule’s condition was met, and can trigger a check-in.
- An investigation records Aegis’s analysis of a problem across check-ins, including the evidence it gathers and the hypotheses it evaluates. You can inspect investigations in the web UI.
Reports and Recommendations
Aegis produces two kinds of output: reports that describe the cluster and its workload, and recommendations that describe actions for you to take.Reports
Aegis maintains two reports for each cluster:- The cluster report describes topology, configuration, resource utilization, and health.
- The workload report describes the workloads running on the cluster and their performance characteristics, such as query throughput and latency.
warehouse and district rows, while the cluster report showed available CPU and disk capacity. Together, the reports distinguished workload contention from resource exhaustion. To reproduce this kind of comparison, see Analyze a workload change through MCP.
Recommendations
A recommendation contains an action, an explanation of why it matters, and the evidence behind it: the metrics, queries, or statistics Aegis observed, and links to relevant CockroachDB documentation. When the action can be expressed as SQL, the recommendation includes the statement for you to review. Examples include adding or dropping an index, changing a cluster setting, or investigating intermittent node restarts using information from outside the cluster. To act on a recommendation:- Review the proposed action and its supporting evidence.
- Apply the change through your normal review and change process.
- Compare subsequent reports and workload behavior with the evidence that prompted the change.
- Mark the recommendation done or dismissed.
Why might there be no recommendations?
A check-in can update the reports without identifying an action to recommend. An empty recommendation list means Aegis found nothing to recommend from what it observed. Read the reports for the observations and explanations behind that result, and for any limits on what Aegis could observe. For example, in the TPC-C test described in Understand transaction contention, Aegis identified candidate indexes but did not recommend them. Its workload report explained that those indexes targeted queries contributing little to the workload’s execution time and would not address the dominant row contention. The report explained the performance issue without proposing an index change.Adaptive Learning
Aegis uses its history of observations, reports, investigations, and recommendations to keep its analysis specific to your cluster. For example, it detects a workload change by comparing current activity with an earlier report, and it remembers which recommendations it has already made. You can add your own context with Custom Instructions, which Aegis includes in every check-in. In the cluster workspace, go to Custom instructions, enter the context, and click Save. Use custom instructions to add business context that Aegis can’t get from the cluster directly, such as a known issue, an intentional configuration choice, a planned migration, or an occasional analytics workload whose longer-running queries are expected. Adaptive learning means accumulating and using this cluster-specific context during analysis. Your cluster metadata and interactions with Aegis are not used to train or fine-tune AI models. For more information, see How Aegis uses AI.Use the Aegis web UI
The Aegis web UI provides a place to review the connected cluster’s state, explore the evidence behind a recommendation, and ask questions through Ask Aegis. To give your own agents access to the same context using tools such as MCP, see Agentic Ecosystem.Open a cluster workspace
After you enroll and connect a cluster, sign in to Aegis with your CockroachDB Cloud account and open the cluster’s workspace. The cluster name appears in the workspace header. For prerequisites, see Security and Administration. Home summarizes the latest reported cluster and workload state, open recommendations, and recent check-ins.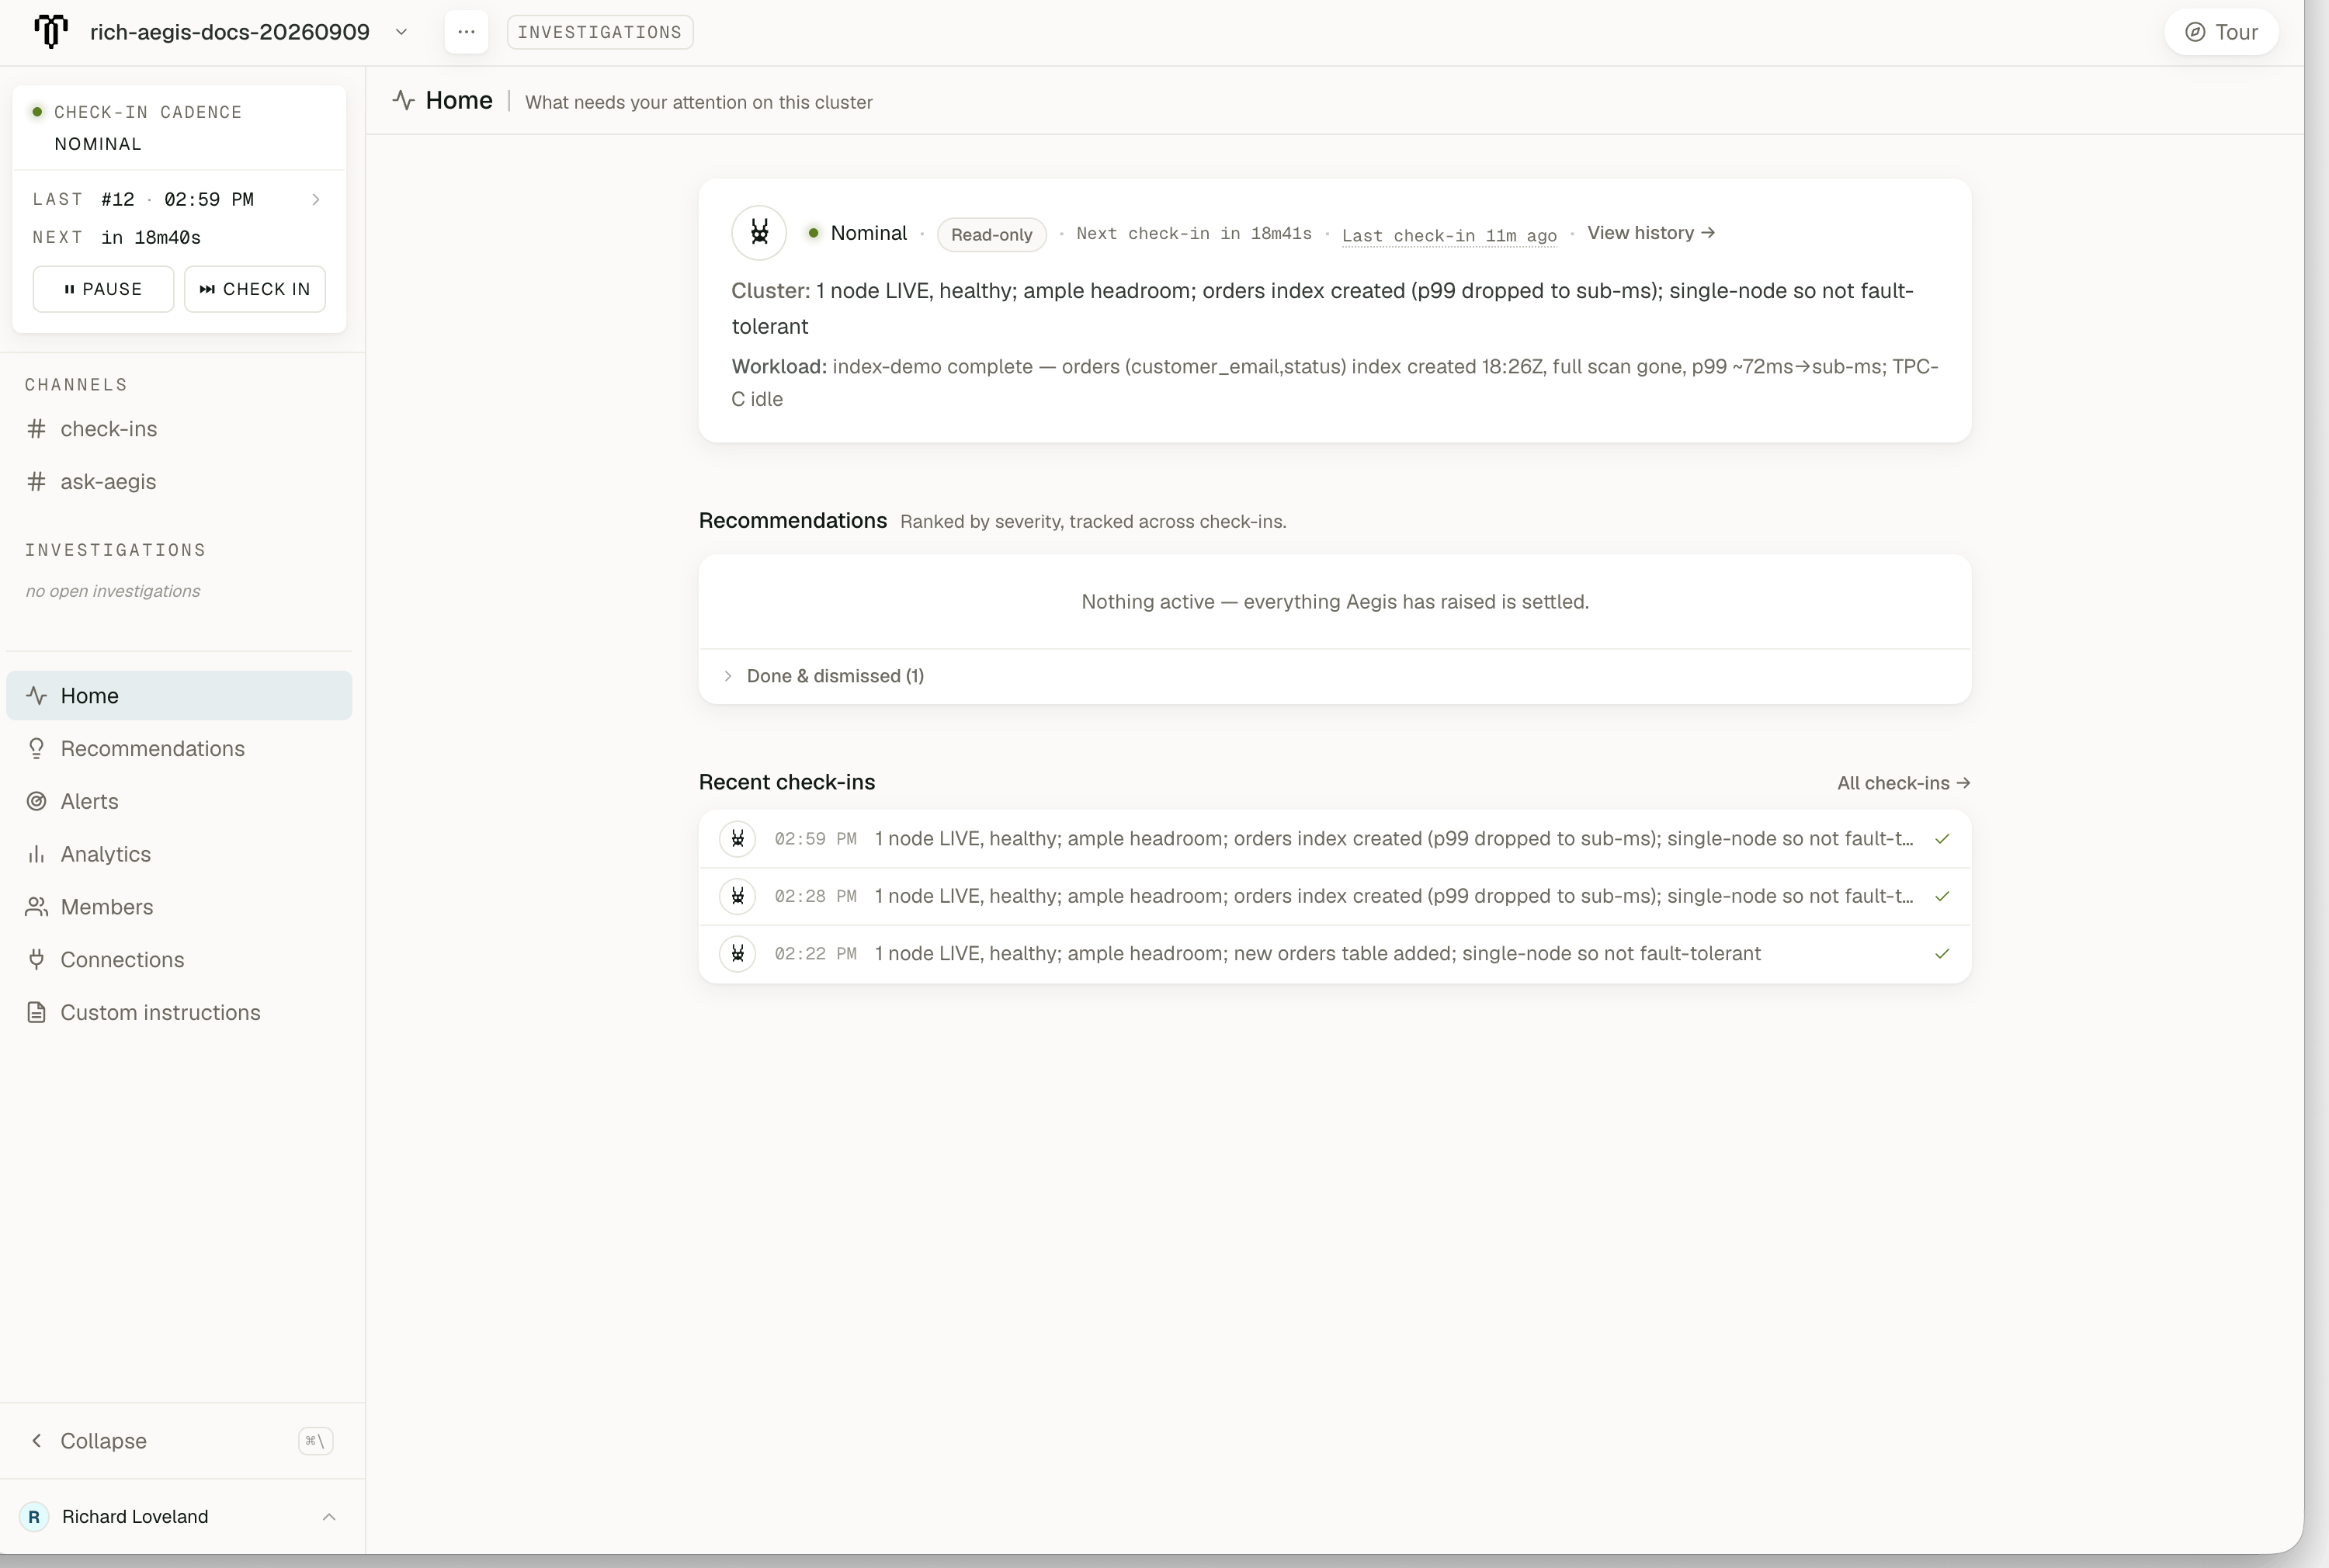
Find reports, recommendations, and activity
Use the workspace navigation to find the information relevant to your task: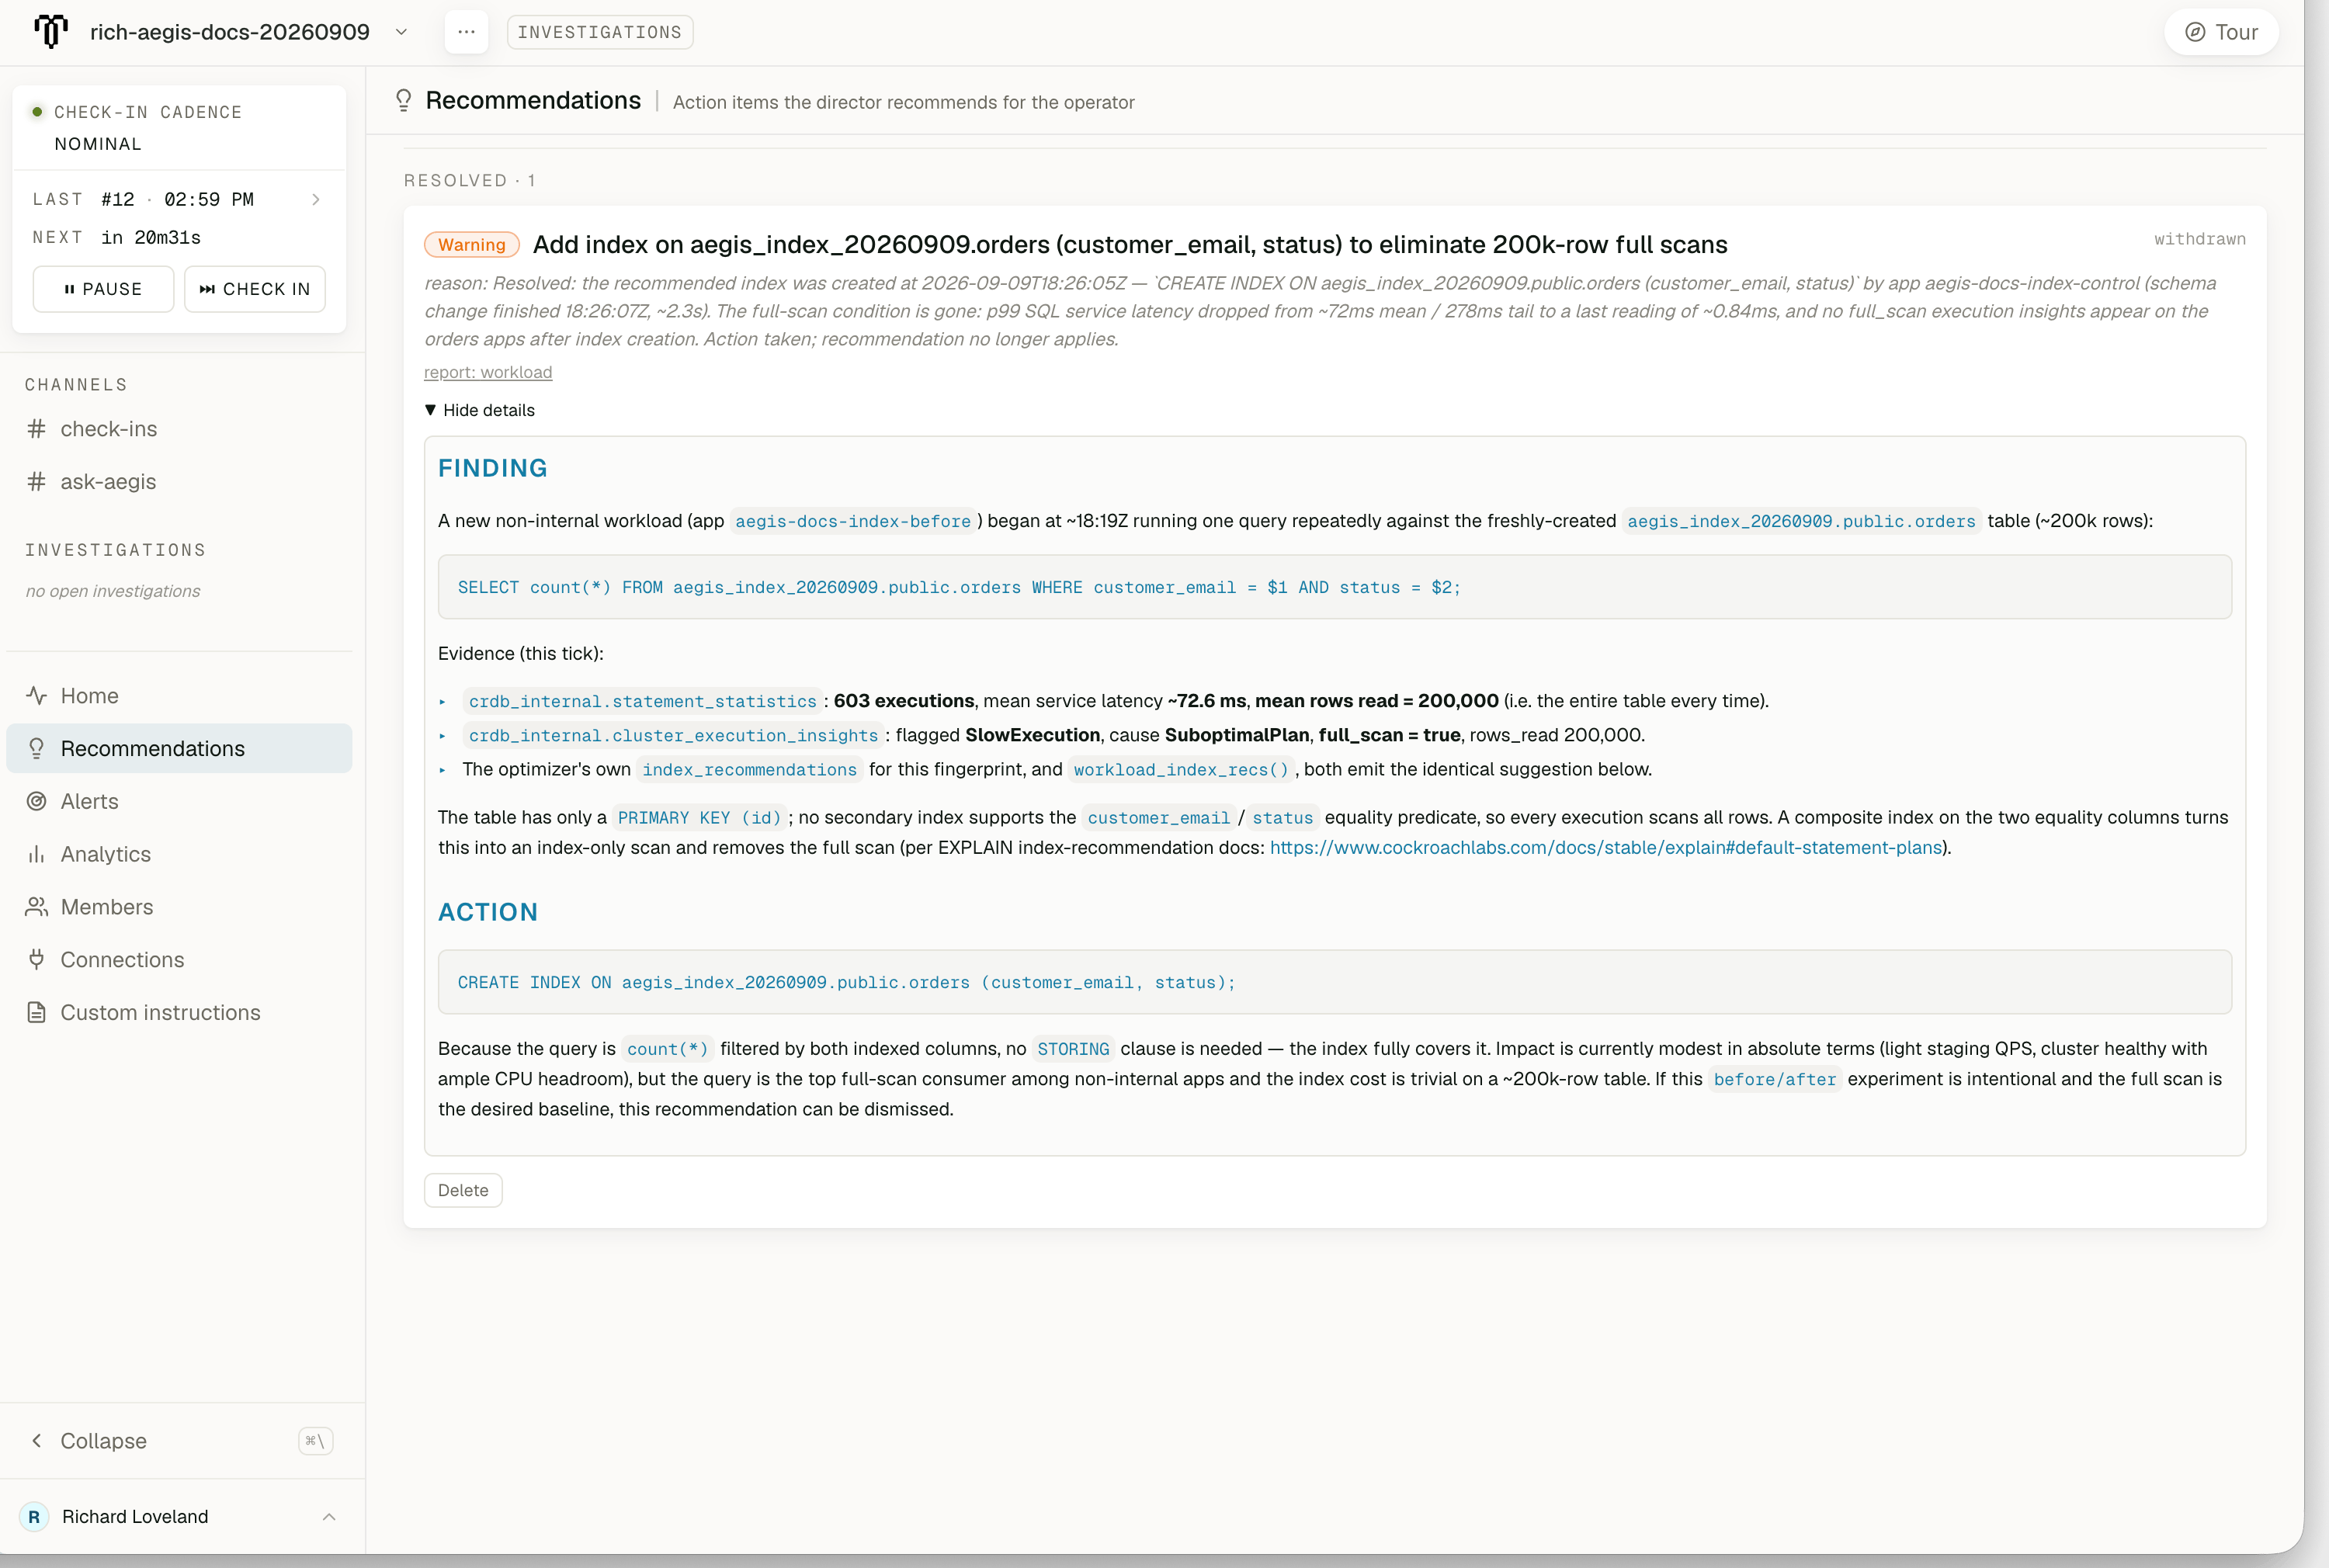
withdrawn, and records the reason the action no longer applies.
When investigations are open, they appear in the Investigations section. For more information, see Intelligent Alerting and Investigations.
To request a check-in from the workspace, click Check in in the Check-in cadence panel.
For worked examples of interpreting contention and acting on an index recommendation, see Aegis Example Workflows.
Ask Aegis: Cluster-aware Q&A
To open Ask Aegis, select #ask-aegis in the workspace’s Channels section. Ask a question about the cluster, or follow up on a report or recommendation. Ask Aegis has access to the same cluster context and tools that Aegis uses during check-ins, and it can consult the CockroachDB documentation to explain its answers. For example, ask:- How is this cluster looking overall right now?
- What changed in this cluster’s workload since the previous check-in?
- What evidence supports this index recommendation?
- What did the investigation find about the increase in latency?