

Query issues
Hanging or stuck queries
When you experience a hanging or stuck query and the cluster is healthy (i.e., no unavailable ranges, network partitions, etc), the cause could be a long-running transaction holding write intents or locking reads on the same rows as your query. Such long-running queries can hold locks for (practically) unlimited durations. If your query tries to access those rows, it must wait for that transaction to complete (by committing or rolling back) before it can make progress. Until the transaction is committed or rolled back, the chances of concurrent transactions internally retrying and throwing a retry error increase. Refer to the performance tuning recipe for identifying and unblocking a waiting transaction. If you experience this issue on a CockroachDB Standard or Basic cluster, your cluster may be throttled or disabled because you’ve reached your monthly resource limits.Identify slow queries
You can identify high-latency SQL statements on the Insights or Statements pages in the DB Console. If these graphs reveal latency spikes, CPU usage spikes, or slow requests, these might indicate slow queries in your cluster. You can also enable the slow query log to log all queries whose latency exceeds a configured threshold, as well as queries that perform a full table or index scan. You can collect richer diagnostics of a high-latency statement by creating a diagnostics bundle when a statement fingerprint exceeds a certain latency. If you find queries that are consuming too much memory, cancel the queries to free up memory usage. For information on optimizing query performance, see SQL Performance Best Practices.Visualize statement traces in Jaeger
You can look more closely at the behavior of a statement by visualizing a statement trace in Jaeger. A statement trace contains messages and timing information from all nodes involved in the execution.Run Jaeger
-
Start Jaeger:
This runs the latest version of Jaeger, and forwards two ports to the container.
6831is the trace ingestion port,16686is the UI port. By default, Jaeger will store all received traces in memory.
Import a trace from a diagnostics bundle into Jaeger
-
Activate statement diagnostics on the DB Console Statements Page or run
EXPLAIN ANALYZE (DEBUG)to obtain a diagnostics bundle for the statement. -
Go to
http://localhost:16686. -
Click JSON File in the Jaeger UI and upload
trace-jaeger.jsonfrom the diagnostics bundle. The trace will appear in the list on the right.
-
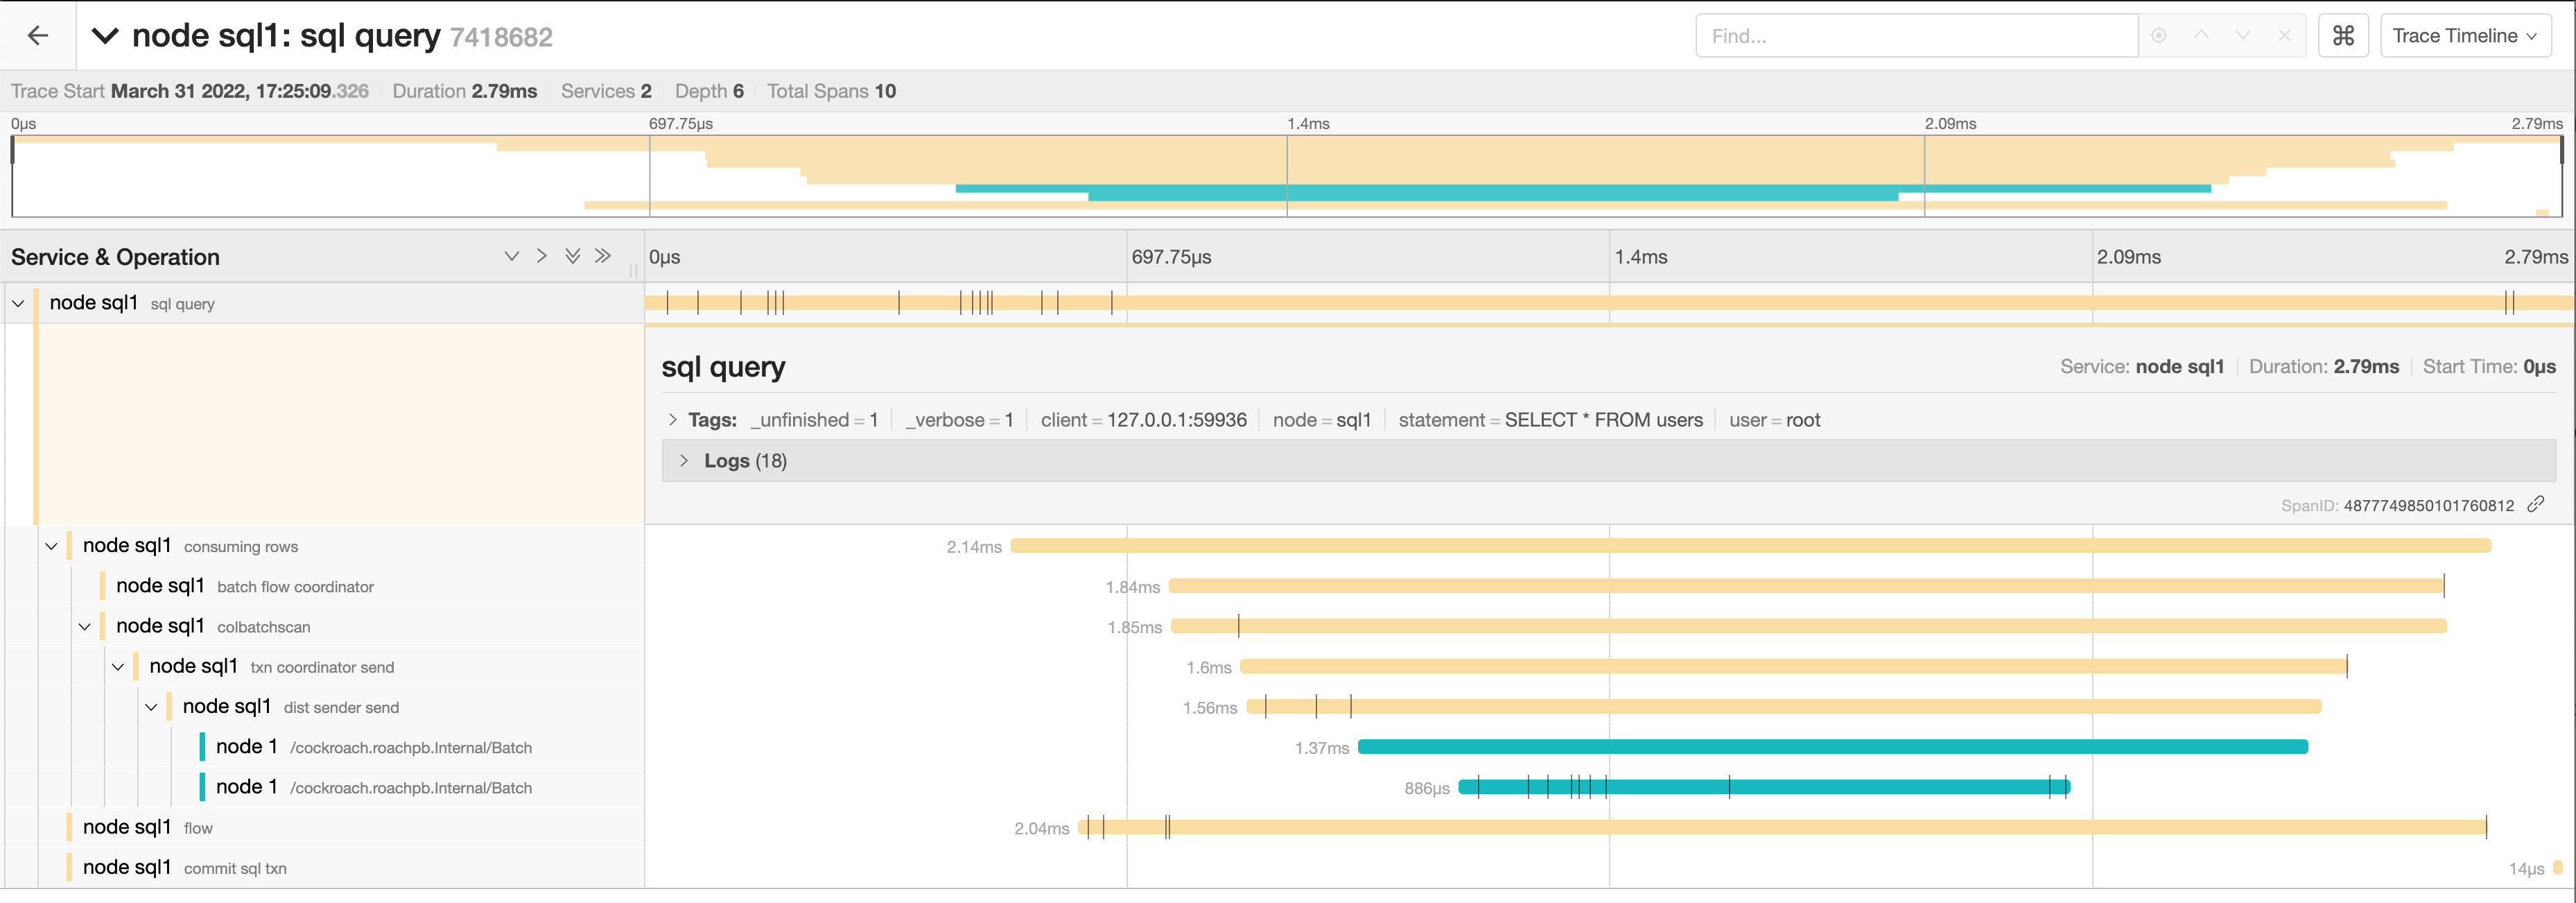
Click the trace to view its details. It is visualized as a collection of spans with timestamps. These may include operations executed by different nodes.
-
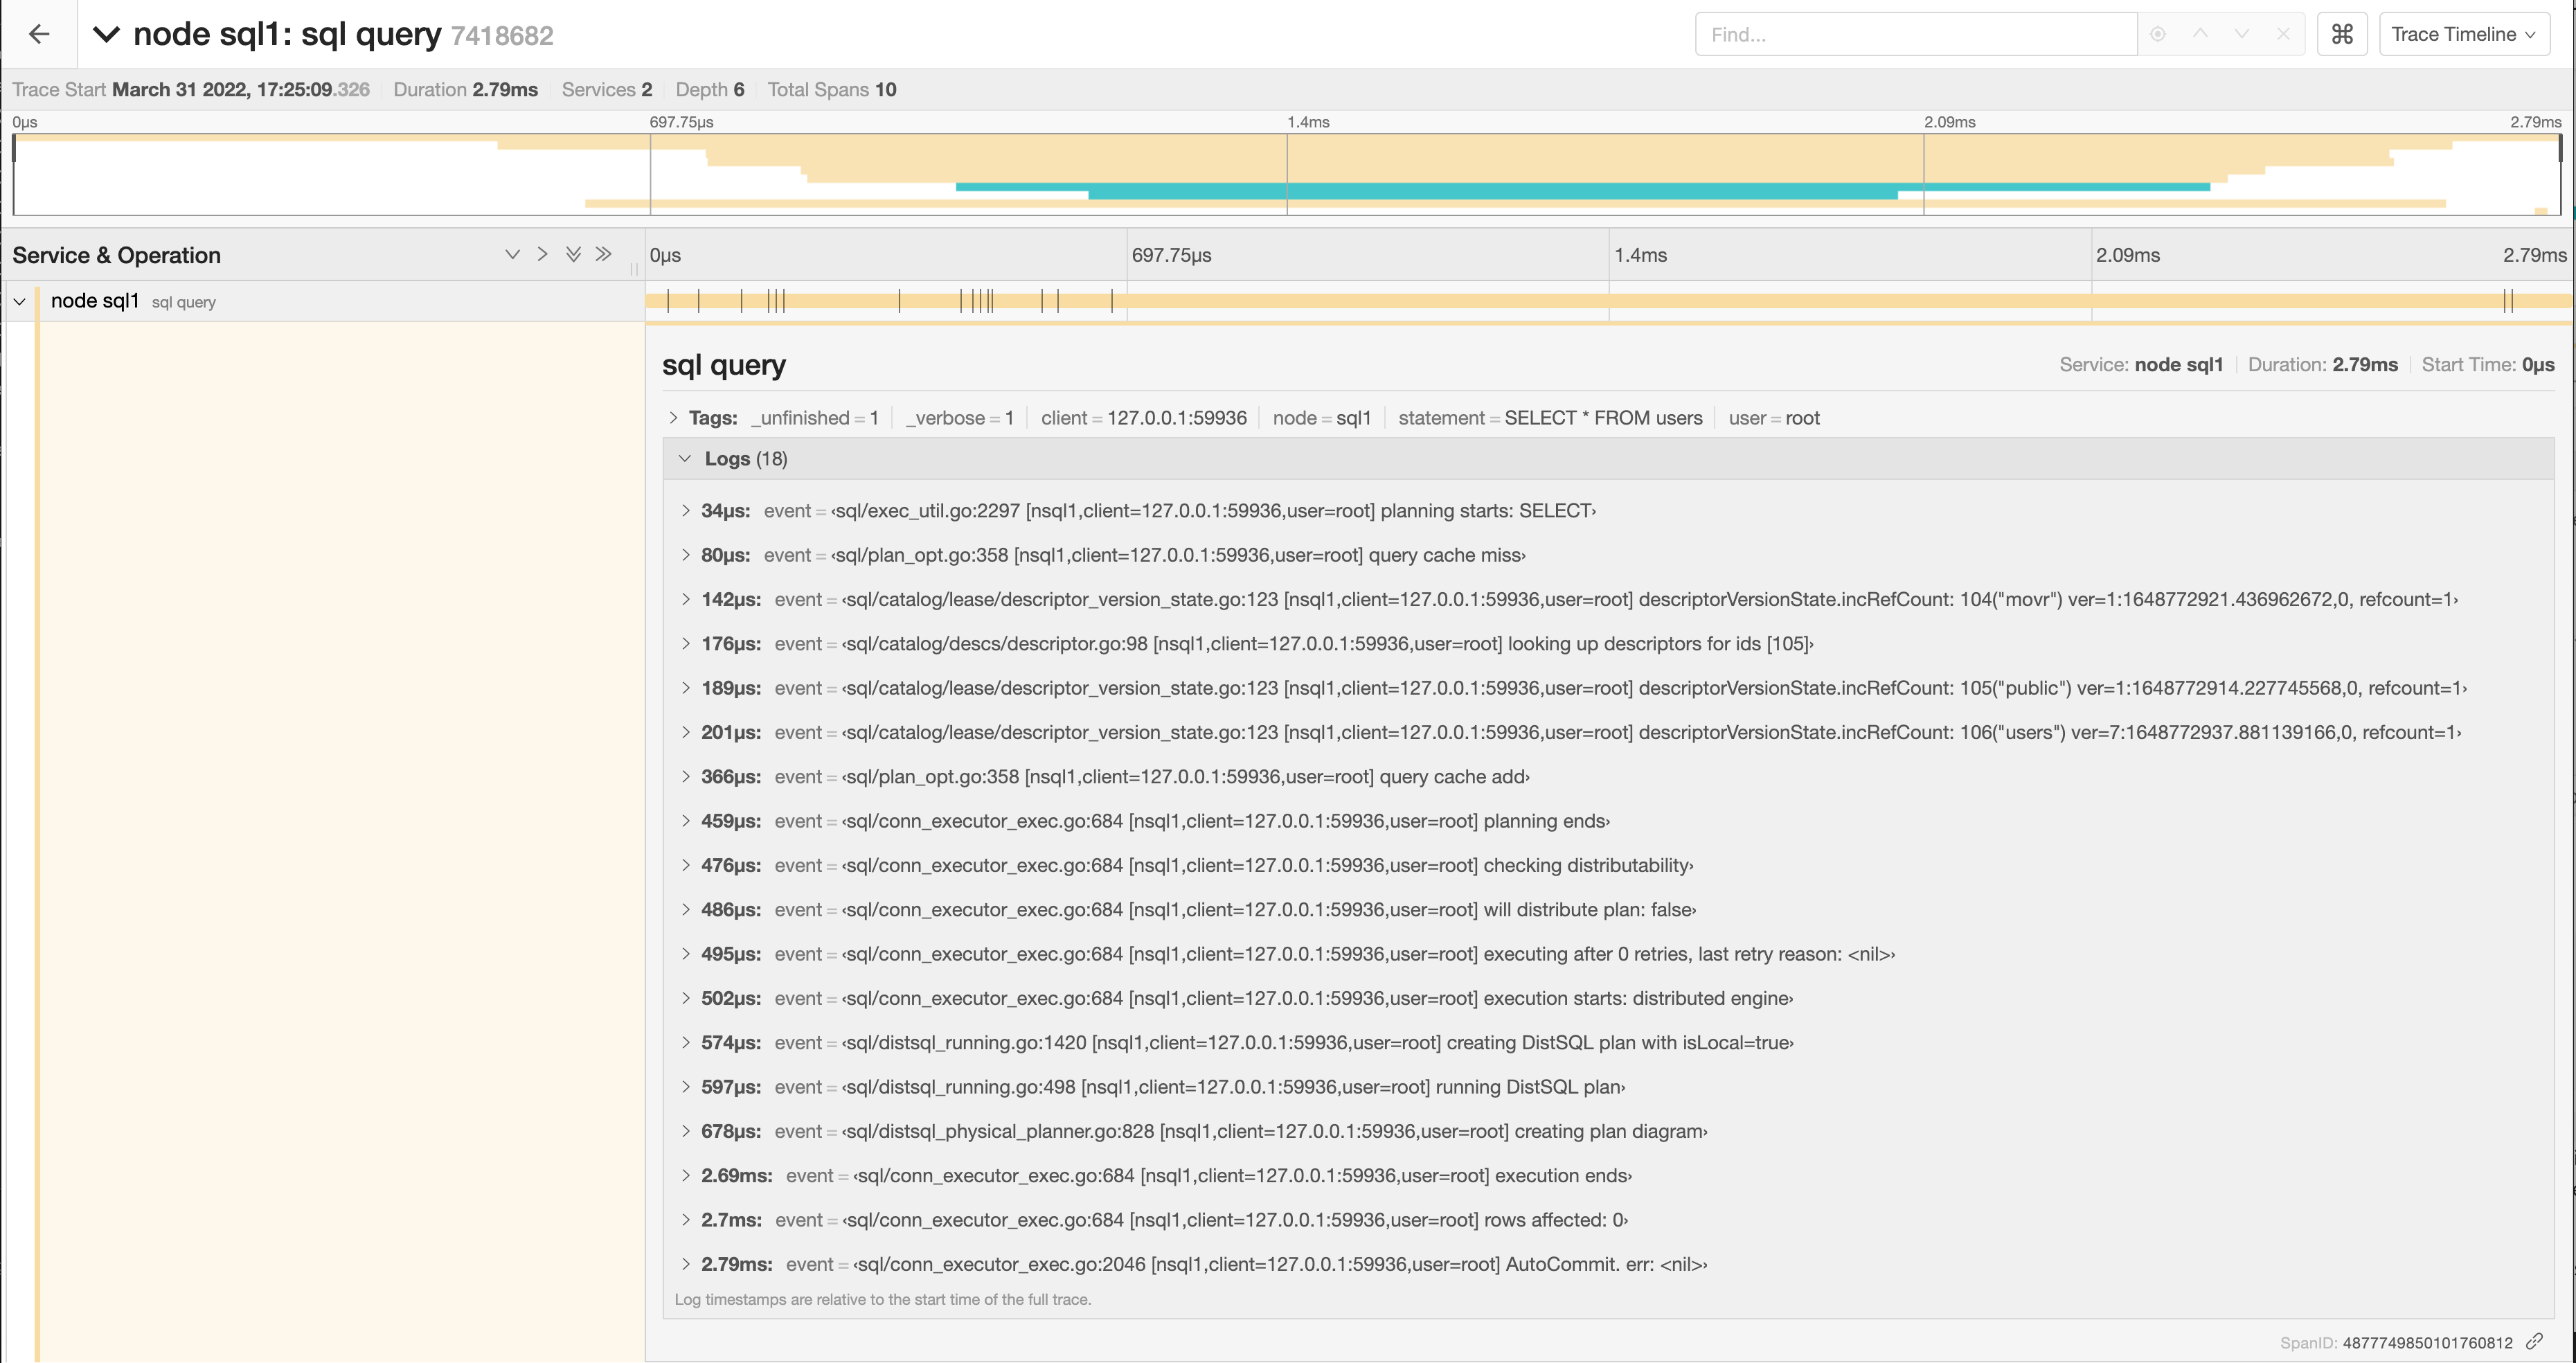
Click a span to view details for that span and log messages.
-
You can troubleshoot transaction contention, for example, by gathering diagnostics on statements with high latency and looking through the log messages in
trace-jaeger.jsonfor jumps in latency. In the following example, the trace shows that there is significant latency between a push attempt on a transaction that is holding a lock (56.85ms) and that transaction being committed (131.37ms).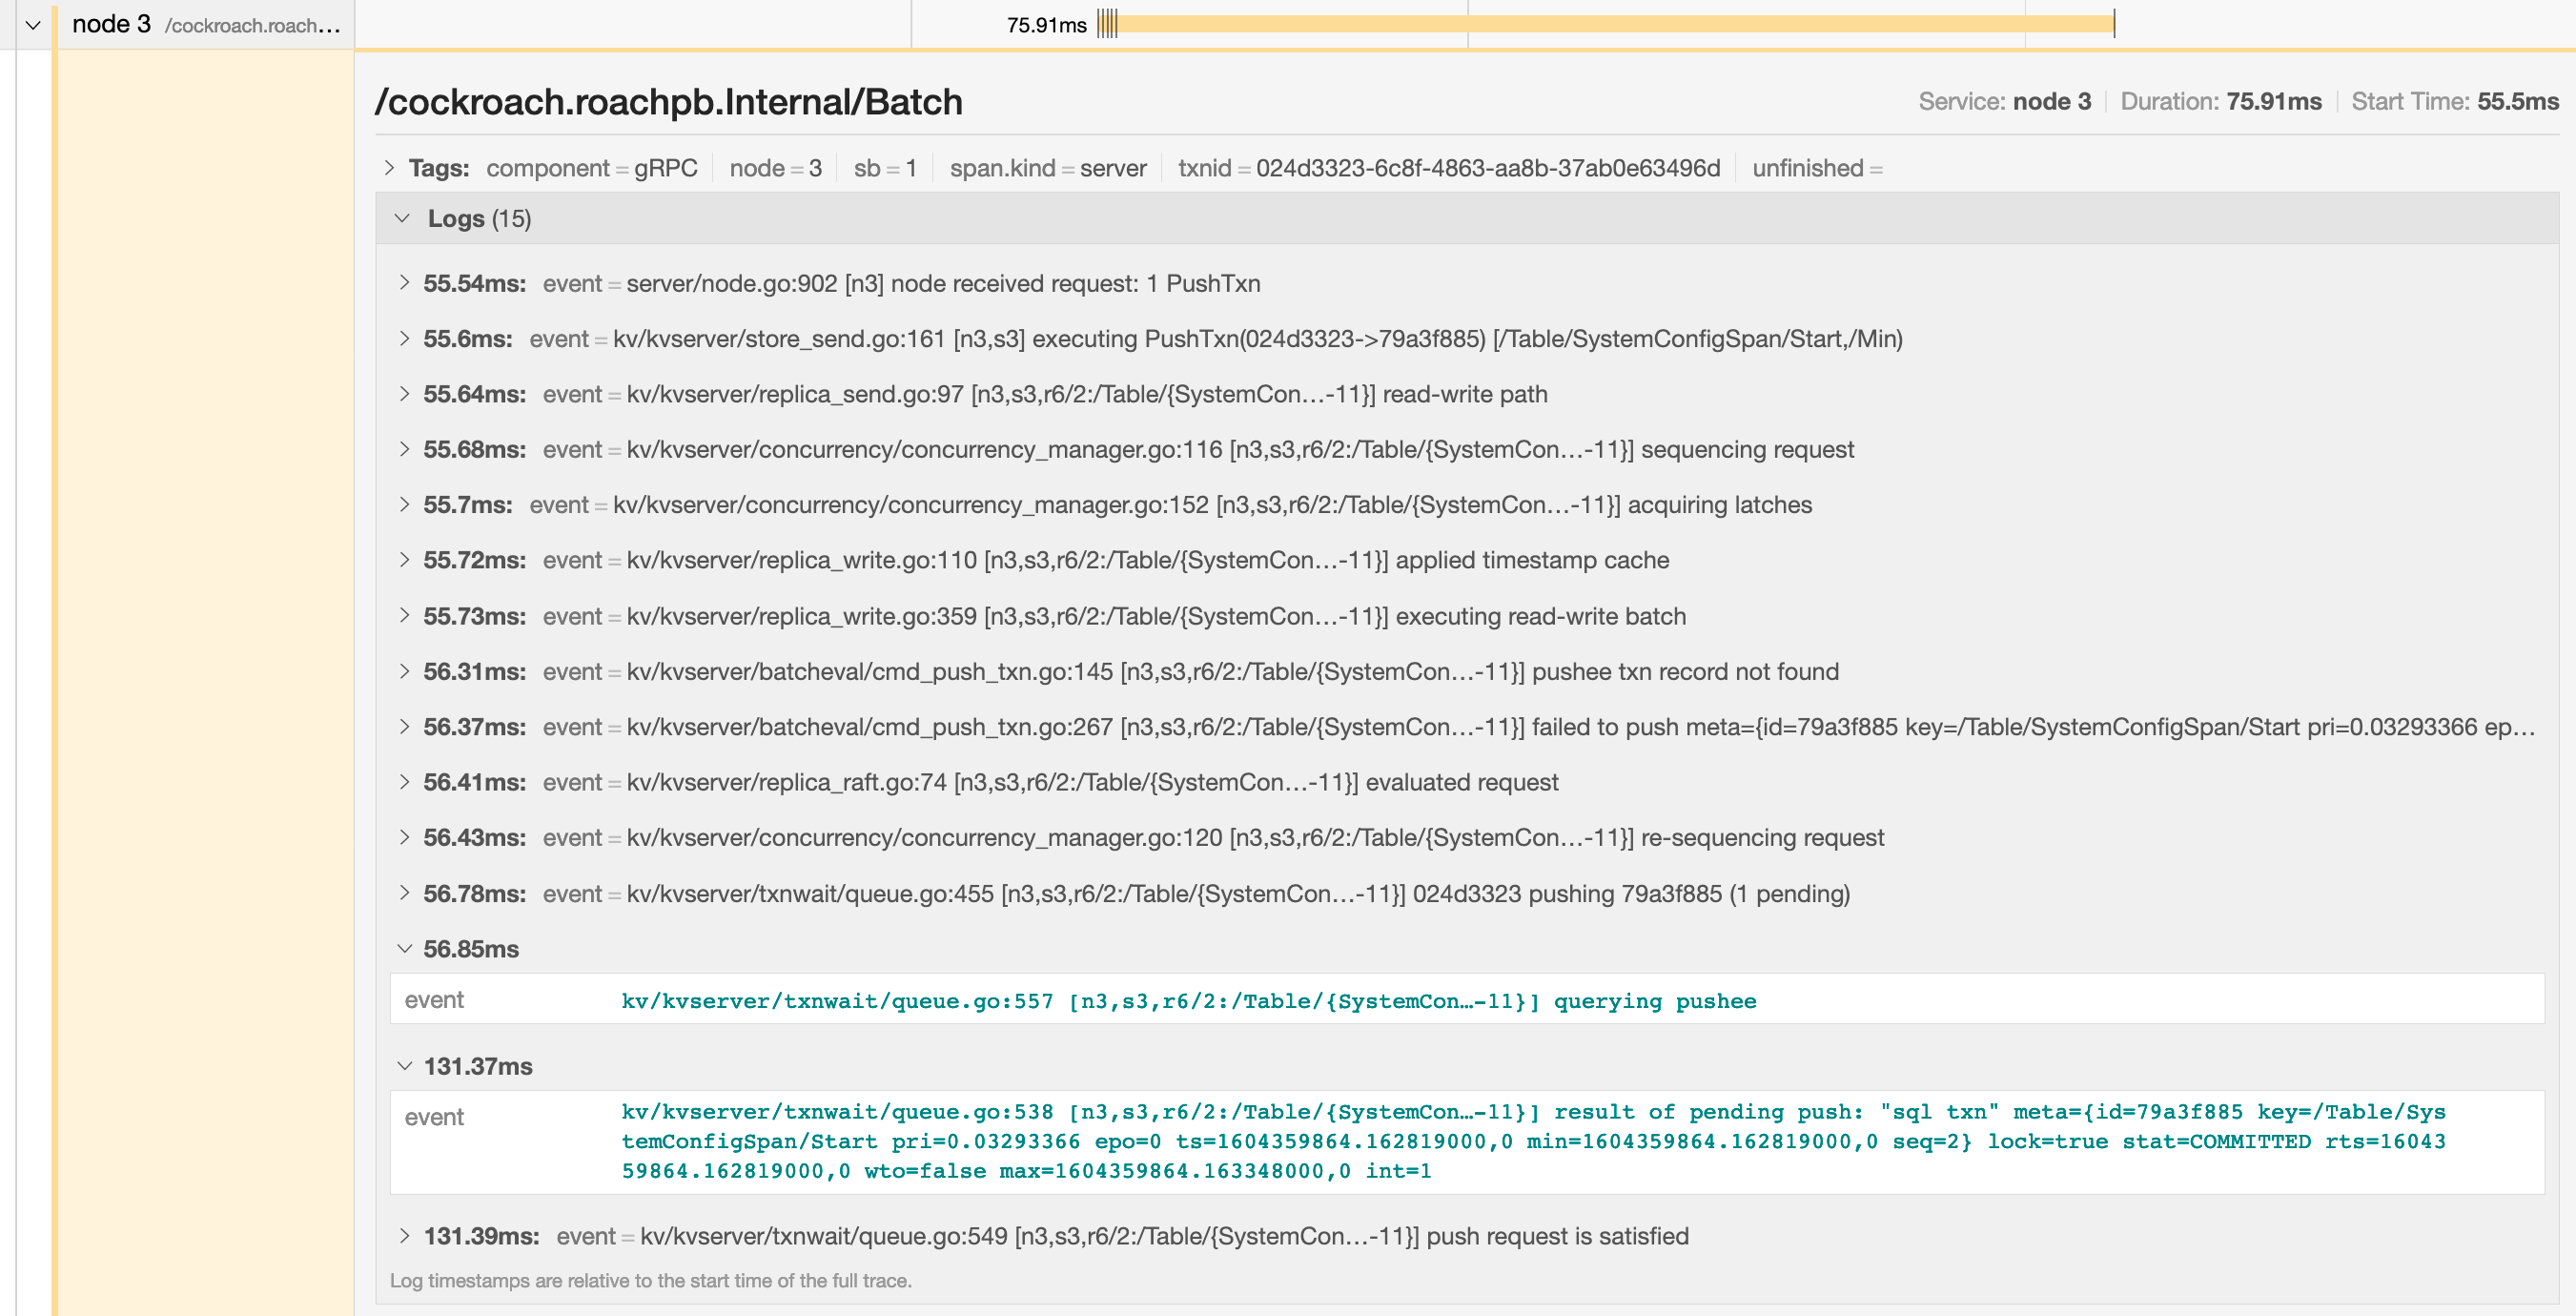
Visualize traces sent directly from CockroachDB
This example shows how to configure CockroachDB to route all traces to Jaeger. For details on sending traces from CockroachDB to Jaeger and other trace collectors, see Configure CockroachDB to send traces to a third-party trace collector.Enabling full tracing is expensive both in terms of CPU usage and memory footprint, and is not suitable for high throughput production environments.
-
Run CockroachDB and set the Jaeger agent configuration:
-
Go to
http://localhost:16686. -
In the Service field, select CockroachDB.
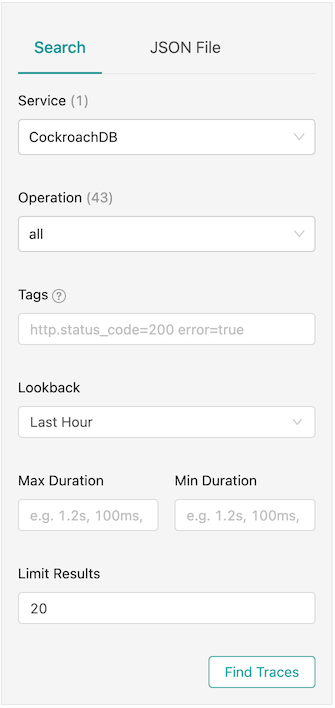
- Click Find Traces.
.log files to correlate events.
Jaeger’s memory storage works well for small use cases, but can result in out of memory errors when collecting many traces over a long period of time. Jaeger also supports disk-backed local storage using Badger. To use this, start Jaeger by running the following Docker command:
Queries are always slow
If you have consistently slow queries in your cluster, use the Statement Fingerprint page to drill down to an individual statement and collect diagnostics for the statement. A diagnostics bundle contains a record of transaction events across nodes for the SQL statement. You can also use anEXPLAIN ANALYZE statement, which executes a SQL query and returns a physical query plan with execution statistics. You can use query plans to troubleshoot slow queries by indicating where time is being spent, how long a processor (i.e., a component that takes streams of input rows and processes them according to a specification) is not doing work, etc.
Cockroach Labs recommends sending either the diagnostics bundle (preferred) or the EXPLAIN ANALYZE output to our support team for analysis.
Queries are sometimes slow
If the query performance is irregular:- Run
SHOW TRACE FOR SESSIONfor the query twice: once when the query is performing as expected and once when the query is slow. - Contact support to help analyze the outputs of the
SHOW TRACEcommand.
SELECT statements are slow
The common reasons for a sub-optimal SELECT performance are inefficient scans, full scans, and incorrect use of indexes. To improve the performance of SELECT statements, refer to the following documents:
SELECT statements with GROUP BY columns are slow
Suppose you have a slow selection query that
- Has a
GROUP BYclause. - Uses an index that has a
STORINGclause. - Where some or all of the columns in the query’s
GROUP BYclause are part of the index’sSTORINGclause and are not index key columns.
GROUP BY clause are organization, os, and version.
The query plan shows that it is using index nodes_lastseen_organization_storing:
nodes_lastseen_organization_storing index has the GROUP BY column organization as an index key column. However, the STORING clause includes the GROUP BY columns os and version.
Solution
Create a new secondary index that has all of theGROUP BY columns as key columns in the index.
GROUP BY rather than a hash GROUP BY. After you make this change, you should notice an improvement in the latency of the example query.
INSERT and UPDATE statements are slow
Use the Statements page to identify the slow SQL statements.
Refer to the following pages to improve INSERT and UPDATE performance:
Cancel running queries
See Cancel long-running queries.Low throughput
Throughput is affected by the disk I/O, CPU usage, and network latency. Use the DB Console to check the following metrics:- Disk I/O: Disk IOPS in progress
- CPU usage: CPU percent
- Network latency: Network Latency
Query runs out of memory
If your query returns the error codeSQLSTATE: 53200 with the message ERROR: root: memory budget exceeded, follow the guidelines in memory budget exceeded.
Transaction retry errors
Messages with the error code40001 and the string restart transaction are known as transaction retry errors. These indicate that a transaction failed due to contention with another concurrent or recent transaction attempting to write to the same data. The transaction needs to be retried by the client.
In most cases, the correct actions to take when encountering transaction retry errors are:
- Update your application to support client-side retry handling when transaction retry errors are encountered. Follow the guidance for the specific error type.
- Take steps to minimize transaction retry errors in the first place. This means reducing transaction contention overall, and increasing the likelihood that CockroachDB can automatically retry a failed transaction.
Unsupported SQL features
CockroachDB has support for most SQL features. Additionally, CockroachDB supports the PostgreSQL wire protocol and the majority of its syntax. This means that existing applications can often be migrated to CockroachDB without changing application code. However, you may encounter features of SQL or the PostgreSQL dialect that are not supported by CockroachDB. For example, the following PostgreSQL features are not supported:CREATE DOMAIN
CockroachDB does not support CREATE DOMAIN.
PostgreSQL range types
CockroachDB does not support PostgreSQL range types.Other unsupported features
- Triggers. These must be implemented in your application logic.
- Events.
- Drop primary key.
Each table must have a primary key associated with it. You can drop and add a primary key constraint within a single transaction.
- XML functions.
- Column-level privileges.
- XA syntax.
- Creating a database from a template.
- Dropping a single partition from a table.
- Foreign data wrappers.
- Advisory Lock Functions (although some functions are defined with no-op implementations).
Node issues
Single hot node
A hot node is one that has much higher resource usage than other nodes. To determine if you have a hot node in your cluster, access the DB Console and check the following:- Click Metrics and navigate to the following graphs. Hover over each graph to see the per-node values of the metrics. If one of the nodes has a higher value, you have a hot node in your cluster.
- Replication dashboard > Average Queries per Store graph
- Overview dashboard > Service Latency graph
- Hardware dashboard > CPU Percent graph
- SQL dashboard > SQL Connections graph
- Hardware dashboard > Disk IOPS in Progress graph
- Open the Hot Ranges page and check for ranges with significantly higher QPS on any nodes.
Solution
- If you have a small table that fits into one range, then only one of the nodes will be used. This is expected behavior. However, you can split your range to distribute the table across multiple nodes.
- If the SQL Connections graph shows that one node has a higher number of SQL connections and other nodes have zero connections, check if your app is set to talk to only one node.
- Check load balancer settings.
- Check for transaction contention.
- If you have a monotonically increasing index column or primary Key, then your index or primary key should be redesigned. For more information, see Unique ID best practices.
- If a range has significantly higher QPS on a node, there may be a hot spot on the range that needs to be reduced. For more information, see Hot spots.
- If you have a monotonically increasing index column or primary key, then your index or primary key should be redesigned. See Unique ID best practices for more information.
Per-node queries per second (QPS) is high
If a cluster is not idle, it is useful to monitor the per-node queries per second. CockroachDB will automatically distribute load throughout the cluster. If one or more nodes is not performing any queries there is likely something to investigate. Seeexec_success and exec_errors which track operations at the KV layer and sql_{select,insert,update,delete}_count which track operations at the SQL layer.
Increasing number of nodes does not improve performance
See Why would increasing the number of nodes not result in more operations per second?bad connection and closed responses
A response of bad connection or closed normally indicates that the node to which you are connected has terminated. You can check this by connecting to another node in the cluster and running cockroach node status.
Once you find the node, you can check its logs (stored in cockroach-data/logs by default).
Because this kind of behavior is unexpected, you should contact Support.
Log queries executed by a specific node
If you are testing CockroachDB locally and want to log queries executed by a specific node, you can either pass a CLI flag at node startup or execute a SQL function on a running node. Using the CLI to start a new node, use the--vmodule flag with the cockroach start command. For example, to start a single node locally and log all client-generated SQL queries it executes, run:
crdb_internal.set_vmodule() function:
DEV logging channel, which outputs by default to the primary cockroach log file in /cockroach-data/logs. Use the symlink cockroach.log to open the most recent log.
Configure CockroachDB to send traces to a third-party trace collector
You can configure CockroachDB to send traces to a third-party collector. CockroachDB supports Jaeger, Zipkin, and any trace collector that can ingest traces over the standard OTLP protocol. Enabling tracing also activates all the log messages, at all verbosity levels, as traces include the log messages printed in the respective trace context. Enabling full tracing is expensive both in terms of CPU usage and memory footprint, and is not suitable for high throughput production environments. You can configure the CockroachDB tracer to route to the OpenTelemetry tracer, with OpenTelemetry being supported by all observability tools. In particular, you can configure CockroachDB to output traces to:- A collector that uses the OpenTelemetry Protocol (OTLP).
- The OpenTelemetry (OTEL) collector, which can in turn route them to other tools. The OTEL collector is a canonical collector, using the OTLP protocol, that can buffer traces and perform some processing on them before exporting them to Jaeger, Zipkin, and other OTLP tools.
- Jaeger or Zipkin using their native protocols. This is implemented by using the Jaeger and Zipkin dedicated “exporters” from the OTEL SDK.
Troubleshoot SQL client application problems
High client CPU load, connection pool exhaustion, or increased connection latency when SCRAM password-based authentication is enabled
Overview
When SASL/SCRAM-SHA-256 Secure Password-based Authentication (SCRAM Authentication) is enabled on a cluster, some additional CPU load is incurred on client applications, which are responsible for handling SCRAM hashing. It’s important to plan for this additional CPU load to avoid performance degradation, CPU starvation, and connection pool exhaustion on the client. For example, the following set of circumstances can exhaust the client application’s resources:- SCRAM Authentication is enabled on the cluster (the
server.user_login.password_encryptioncluster setting is set toscram-sha-256). - The client driver’s connection pool has no defined maximum number of connections, or is configured to close idle connections eagerly.
- The client application issues transactions concurrently.
Mitigation steps while keeping SCRAM enabled
To mitigate against this situation while keeping SCRAM authentication enabled, Cockroach Labs recommends that you:- Test and adjust your workloads in batches when migrating to SCRAM authentication.
- Start by enabling SCRAM authentication in a testing environment, and test the performance of your client application against the types of workloads you expect it to handle in production before rolling the changes out to production.
- Limit the maximum number of connections in the client driver’s connection pool.
- Limit the maximum number of concurrent transactions the client application can issue.
Lower default hashing cost and reapply the password
To decrease the CPU usage of SCRAM password hashing while keeping SCRAM enabled:-
Set the
server.user_login.password_hashes.default_cost.scram_sha_256cluster setting to4096: -
Make sure the
server.user_login.rehash_scram_stored_passwords_on_cost_change.enabledcluster setting is set totrue(the default).
Downgrade from SCRAM authentication
As an alternative to the mitigation steps listed above, you can downgrade from SCRAM authentication to bcrypt as follows:-
Set the
server.user_login.password_encryptioncluster setting tocrdb-bcrypt: -
Ensure the
server.user_login.downgrade_scram_stored_passwords_to_bcrypt.enabledcluster setting is set totrue:
The
server.user_login.upgrade_bcrypt_stored_passwords_to_scram.enabled cluster setting can be left at its default value of true.Something else?
Try searching the rest of our docs for answers:- Connect to a CockroachDB Cluster
- Run Multi-Statement Transactions
- Optimize Statement Performance Overview
- Common Errors and Solutions
- Transactions
- Client-side transaction retry handling
- SQL Layer