

- Simulate a multi-region CockroachDB cluster on your local machine.
- Run a workload on the cluster using our fictional vehicle-sharing application called MovR.
- See the effects of network latency on SQL query performance in the default (non-multi-region) configuration.
- Configure the cluster for good multi-region performance by issuing SQL statements that choose the right survival goals and table localities.
Considerations
This page describes a demo cluster; it does not show best practices for a production deployment. For more information about production deployments of multi-region applications, see Orchestrate CockroachDB Across Multiple Kubernetes Clusters and the Production Checklist. Because the instructions on this page describe how to simulate a multi-region cluster on a single machine, the absolute performance numbers described below are not reflective of the performance you can expect of single-point reads and writes against CockroachDB in a production setting. Instead, the instructions are designed with the following goals:- To show the relative magnitude of the performance improvements to expect when you configure a multi-region cluster correctly.
- To be as easy to try as possible with minimal configuration and setup.
Before you begin
Make sure you have:- A basic understanding of the MovR application
- Docker installed on the local machine
A basic understanding of the MovR application
The workload you’ll run against the cluster is our open-source, fictional, peer-to-peer vehicle-sharing app, MovR. Each instance represents users in a specific region:europe-west1, covering the cities of Amsterdam, Paris, and Rome.us-east1, covering the cities of New York, Boston, and Washington, D.C.us-west1, covering the cities of Los Angeles, San Francisco, and Seattle.
The MovR schema
The six tables in themovr database store user, vehicle, and ride data for MovR:
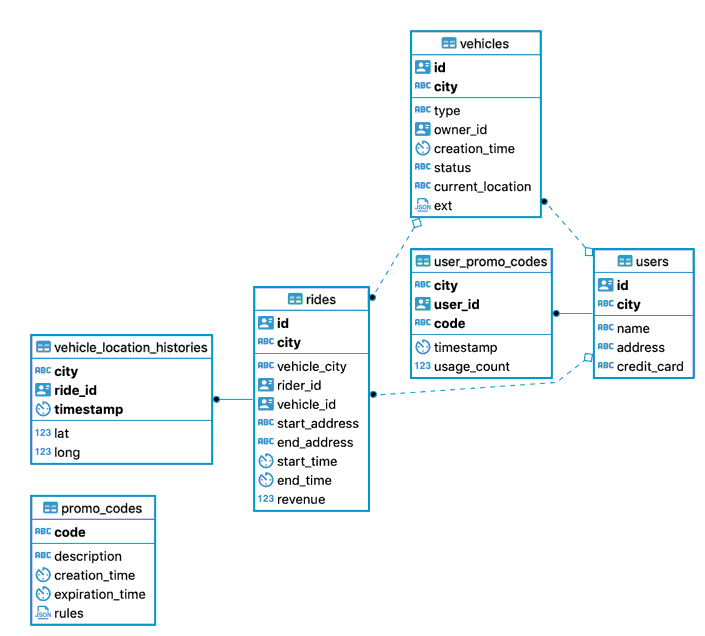
promo_codes have a composite primary key of city and id, in that order. This means that the rows in these tables are ordered by their geography. These tables are read from and written to very frequently. To keep read and write latency low, you’ll use the REGIONAL BY ROW table locality pattern for these tables.
The data in the promo_codes table is different: it is not tied to geography, and it is rarely updated. This type of table is often referred to as a “reference table” or “lookup table”. In this case, you’ll use the Global table locality pattern to keep read latencies low.
For a description of the sequence of SQL statements issued by the MovR application in response to user actions, see How the MovR application works.
Step 1. Simulate a multi-region cluster
Use the followingcockroach demo command to start the cluster. This particular combination of flags results in a demo cluster of 9 nodes, with 3 nodes in each region. It sets the appropriate node localities and also simulates the network latency that would occur between nodes in these localities. For more information about each flag, see the cockroach demo documentation, especially for --global.
- Viewing the DB Console:
http://127.0.0.1:8080. - Connecting to the database from a SQL shell or a programming language:
postgres://root@127.0.0.1:26257?sslmode=disable.
us-west1 and europe-west1 should be in the 150 ms range.
Step 2. Determine node locations
To determine which nodes are in which regions, you will need to refer to two (2) things:- The output of the
\demo lsfrom the SQL shell, which shows the TCP ports on the local machine that we will connect to from the MovR application. - The node IDs shown on the Network Latency Page.
\demo ls from the SQL shell.
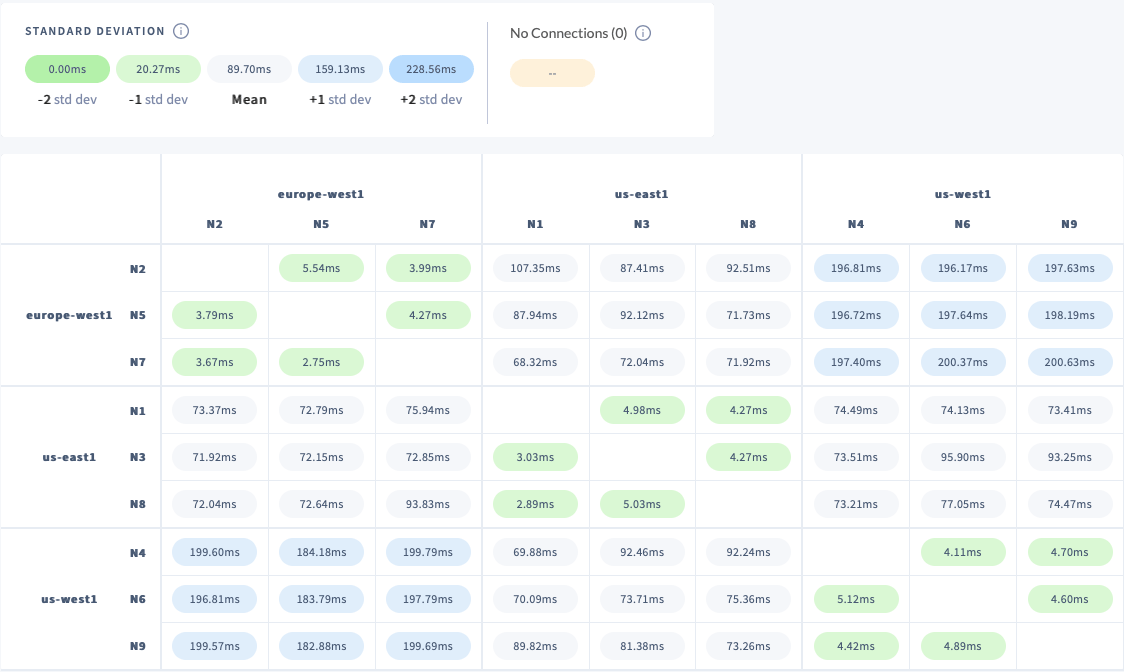
\demo ls and the Network Latency Page that the cluster has the following region/node/port correspondences, which we can use to determine how to connect MovR from various regions:
Step 3. Load and run MovR
Follow these steps to start 3 instances of MovR. Each instance is pointed at a node in a different region. This will simulate load from that region.-
In the SQL shell, create the
movrdatabase: -
Open a second terminal and run the command below to populate the MovR data set. The options are mostly self-explanatory. We limit the application to 1 thread because using multiple threads quickly overloads this small demo cluster’s ability to ingest data. As a result, loading the data takes about 90 seconds on a fast laptop.
-
In the same terminal window, run the following command:
-
Open a third terminal and run the following command:
-
Open a fourth terminal and run the following command:
Step 4. Check service latency
Now that you have load hitting the cluster from different regions, check how the service latencies look before you do any multi-region configuration from SQL. This is the “before” case in the “before and after”. In the DB Console at http://127.0.0.1:8080, click Metrics on the left and hover over the Service Latency: SQL, 99th percentile timeseries graph. You should see the effects of network latency on this workload.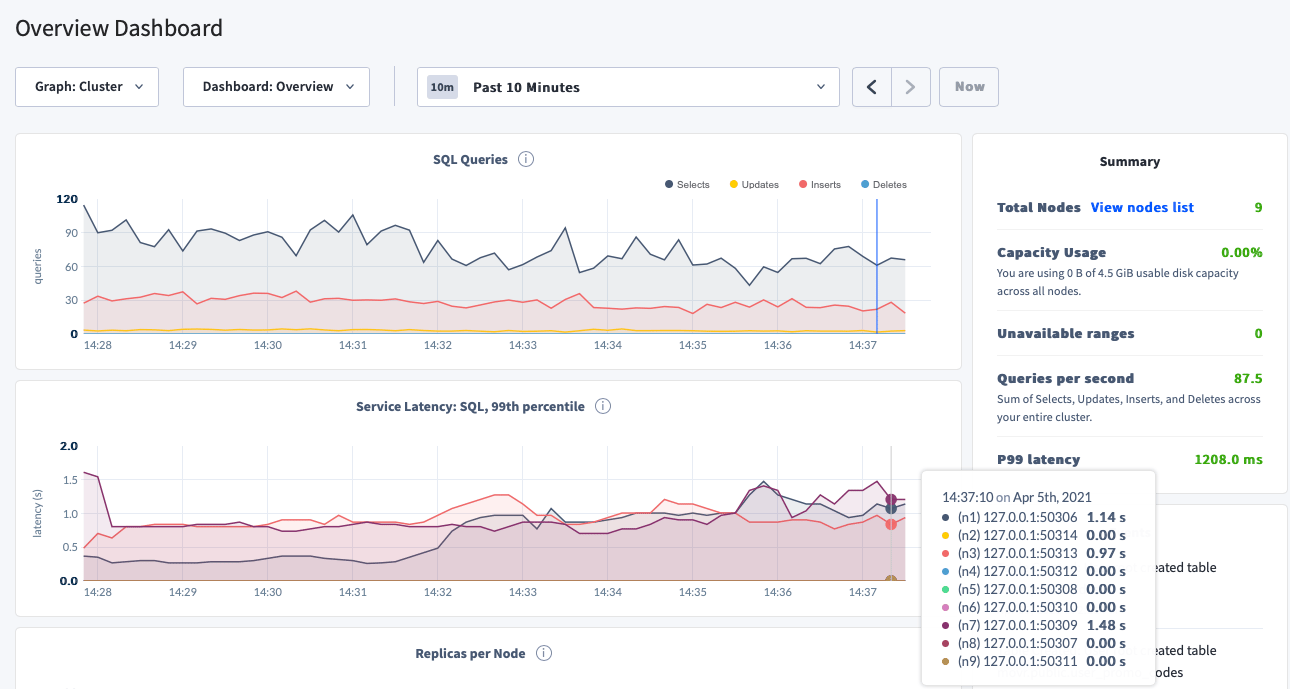
- Round-trip latency between N2 in
europe-west1and N3 inus-east1is 87 ms. - Round-trip latency between N2 in
europe-west1and N4 inus-west1is 196 ms.
Step 5. Execute multi-region SQL statements
The following SQL statements will configure: This information is necessary so that CockroachDB can move data around to optimize access to particular data from particular regions. The main focus is reducing latency in a global deployment. For more information about how this works at a high level, see the Multi-Region Capabilities Overview.The following
ALTER statements will take some seconds to run, since the cluster is under load.Configure database regions
Back in the SQL shell, switch to themovr database:
Configure table localities
Configure GLOBAL tables
As mentioned earlier, all of the tables exceptpromo_codes are geographically specific.
Because the data in promo_codes is not updated frequently (a.k.a., “read-mostly”), and needs to be available from any region, the right table locality is GLOBAL.
user_promo_codes table to have a foreign key into the global promo_codes table. This will enable fast reads of the promo_codes.code column from any region in the cluster.
Configure REGIONAL BY ROW tables
All of the tables exceptpromo_codes contain rows which are partitioned by region, and updated very frequently. For these tables, the right table locality for optimizing access to their data is REGIONAL BY ROW.
Apply this table locality to the remaining tables. These statements use a CASE statement to put data for a given city in the right region and can take around 1 minute to complete for each table.
-
rides -
user_promo_codes -
users -
vehicle_location_histories -
vehicles
Step 6. Re-check service latency
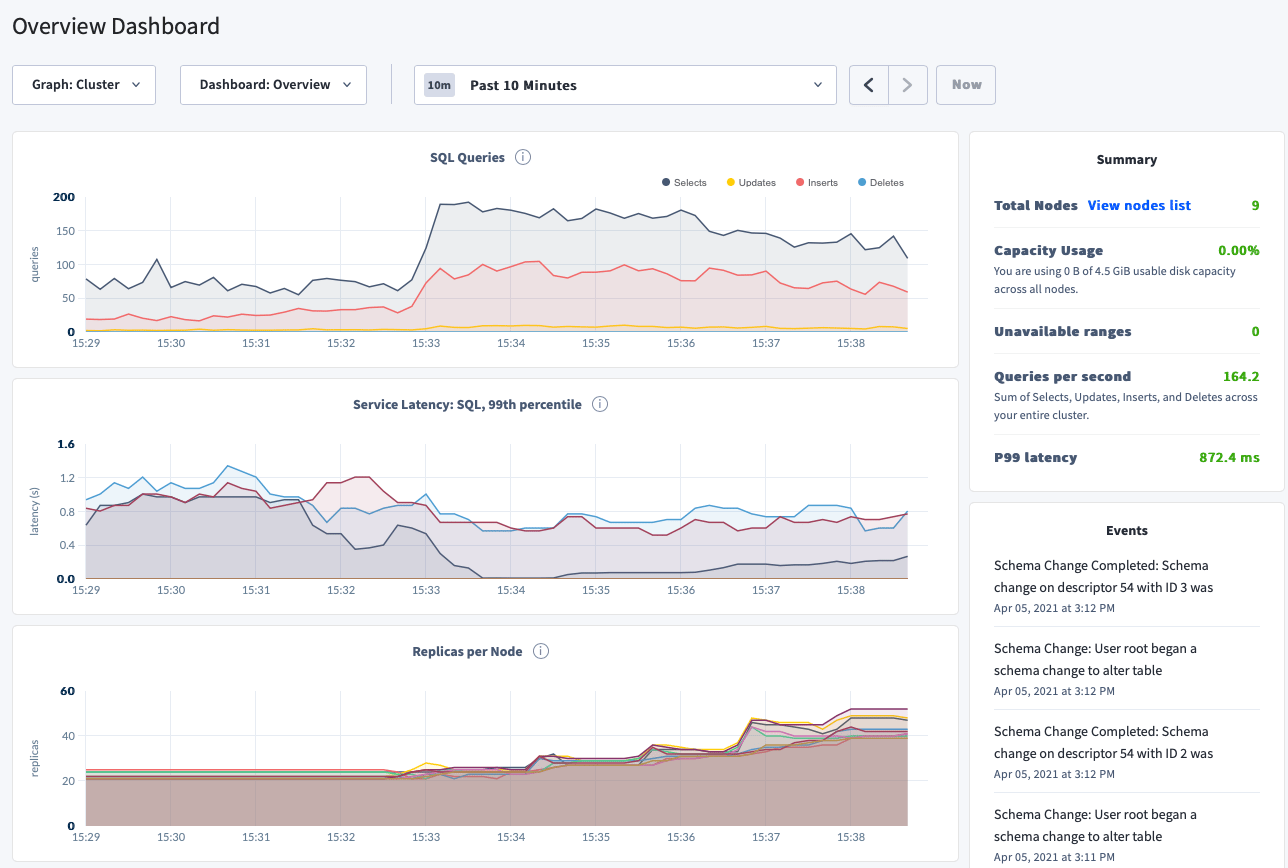
As the multi-region schema changes complete, you should see changes to the following metrics:- SQL Queries: This number should go up, since the cluster can service more load due to better performance (due to better data locality and lower latency). In this particular run, the QPS has almost doubled, from 87 to 164.
- Service Latency: SQL, 99th percentile: In general, even on a small demo cluster like this, the P99 latency should drop and also get less spiky over time, as schema changes finish and data is moved around. For this particular run, the P99 latency has dropped from ~1200 ms to ~870 ms, an over 25% improvement.
- Replicas per Node: This will increase, since the data needs to be spread across more nodes in order to service the multi-region workload appropriately. There is nothing you need to do about this, except to note that it happens, and is required for CockroachDB’s improved multi-region performance features to work.
The small demo cluster used in this example is essentially in a state of overload from the start. The performance numbers shown here only reflect the direction of the performance improvements. You should expect to see much better absolute performance numbers than those described here in a production deployment.
See also
- Multi-Region Capabilities Overview
- How to Choose a Multi-Region Configuration
- When to Use
ZONEvs.REGIONSurvival Goals - When to Use
REGIONALvs.GLOBALTables - Migrate to Multi-Region SQL
- Secondary regions
SET SECONDARY REGIONDROP SECONDARY REGION- Reads and Writes in CockroachDB
- Install CockroachDB